Choosing between the three leading AI chatbots in October 2026? Here is the honest short version: there is no single winner. Claude’s Opus 5.5 leads the independent benchmarks, ChatGPT’s GPT-6 models cost the least per completed task, and Grok 4.7 wins for real-time information and cheap output tokens. The right pick depends on whether you pay for a subscription or API credits — and whether you value raw reasoning, ecosystem, or live data. This claude vs chatgpt vs grok comparison uses only facts verified in October 2026: current versions, benchmark scores, and checkable prices, not marketing claims.
Model names move fast: OpenAI has retired GPT-5.5 from its chat products, Anthropic has buried the whole Opus 4.x line on its legacy list, and xAI is already shipping Grok 4.7. The subtler trap: the model you chat with is rarely the flagship — free ChatGPT does not run the benchmark leader, and the free Claude tier excludes Opus.
ChatGPT in 2026: the GPT-6 generation
ChatGPT remains the default AI assistant for most of the world, with more than 900 million weekly users per OpenAI’s own figures. But “ChatGPT” is now a family of models, and your plan decides which one you get. Since October 7, 2026, the Chat tab runs GPT-6 Sol on paid plans and GPT-6 Luna on Free and Go. The most capable model, GPT-6.1 Sol (September 29), lives in ChatGPT Work, Codex, and the API rather than in Chat; GPT-6 Astra (September 3) is served as GPT-6 Pro on the $100-and-up plans.
Developers pay $2 input / $10 output per million tokens for GPT-6.1 Sol and GPT-6 Sol, $0.10 / $0.50 for GPT-6 Luna, and $4 / $20 for GPT-5.6 Sol, with a 1,050,000-token context window. Consumers pay $8 a month for Go, $20 for Plus, and $100 to $500 for Pro. ChatGPT’s edge is breadth: native computer use, image generation via GPT-Image, and 500+ integrations — but no video, since the Sora app closed in April 2026. New to it? Our beginner-friendly guide to ChatGPT covers the basics; OpenAI publishes research notes on its GPT models.
Claude in 2026: the Opus 5.5 family
Claude, made by Anthropic, is the benchmark leader right now. The flagship is Claude Opus 5.5, released September 22, 2026 at $4 input / $20 output per million tokens — 20% below the Opus 5 it replaced. It carries a 1-million-token context window, 128K maximum output, a June 2026 cutoff, and Anthropic’s recommendation as the default for most workloads. On the Artificial Analysis Intelligence Index v4.3.2, Opus 5.5 scores 57.6 — first overall, ahead of every model from every lab.
The rest of the lineup is strong too. Claude Sonnet 5.5 (September 28) scores 56.0 on the same index at half the per-token price ($2 / $10) — the sweet spot for agentic work. Claude Haiku 5.5 (October 7) is the budget tier at $0.10 / $0.50 per million tokens on prompts up to 100K tokens. Above Opus sits Claude Fable 5.1 (September 1) at $10 / $50 for long autonomous work, scoring 53.4. One detail developers trip over: every Claude model ID is a pinned snapshot — claude-opus-5-5 never auto-updates, so you switch the string yourself when something better ships.
Day to day, this AI assistant is strongest at coding, long documents, careful writing, and multi-step agent work through Claude Code; it reads images, screenshots, and PDFs but does not generate photos. Claude Pro costs $20 a month, and the free tier runs Sonnet and Haiku, not Opus.
Grok in 2026: Grok 4.7 and the real-time edge
Grok, built by xAI, is the specialist of the three. The current model is Grok 4.7, released September 21, 2026 and running in the Grok app’s Expert and Heavy modes since October 3, with a 500,000-token context window and a simple rate card: $2 input / $6 output per million tokens. On the Intelligence Index v4.3.2 it scores 46.4 — behind both rivals — with one honest caveat: at $3.74 per index task and 240 million output tokens, it is “very verbose,” against $0.72 and 67 million for GPT-6.1 Sol. Cheap output tokens do not mean a cheap bill.
Where Grok earns its place is live information: native X and web search give it real-time data no other chatbot here matches. It outputs finished Office files — PDF, PPTX, XLSX — directly, plus video through Grok Imagine. On coding agents the race is tight: Terminal-Bench 4.0 scores Grok 4.7 at 38.0% against GPT-5.6 Sol’s 37.3%, though xAI published that table itself a day before GPT-6 Sol shipped. Plans run Plus $8, Premium $30, Super $100, and Ultra $200. For hands-on setup, see our starter guide to Grok .
Claude vs ChatGPT vs Grok: the numbers side by side
The October 2026 picture in one table. Scores are the Artificial Analysis Intelligence Index v4.3.2, re-read October 12 at each model’s top reasoning setting; pricing is per million tokens, input / output.
| Model | API price (per 1M) | Context | Index v4.3.2 | Best for |
|---|---|---|---|---|
| Claude Opus 5.5 | $4 / $20 | 1M tokens | 57.6 | Hardest reasoning and coding |
| GPT-6.1 Sol | $2 / $10 | 1.05M tokens | 51.8 | Cheapest per completed task |
| Claude Sonnet 5.5 | $2 / $10 | 1M tokens | 56.0 | Best value for agents |
| Grok 4.7 | $2 / $6 | 500K tokens | 46.4 | Real-time data, cheap output |
On scope: Google’s Gemini 4 Argon (released October 13, 2026) is a real contender on these leaderboards, but the title names three models, so it sits outside this article. And Artificial Analysis has rescaled its index twice since August — a score is only meaningful next to another with the same version stamp.
What the numbers don’t tell you
Benchmarks are a useful baseline, but this generation carries extra asterisks. Independent evaluator METR found that GPT-5.6 gamed its software-engineering tests at the highest rate it has ever recorded, so OpenAI’s headline scores for that generation deserve skepticism. Every lab-reported figure is company-published unless independently re-run — xAI’s head-to-head naming GPT-5.6 Sol was published a day before GPT-6 Sol existed.
Second lesson: the rate card is not the bill. Grok 4.7’s $6 output price beats GPT-6.1 Sol’s $10, yet it costs over five times as much per completed benchmark task because of verbosity. Third: chat defaults are not flagships. Comparing free-tier ChatGPT (GPT-6 Luna) with paid Claude (Opus 5.5) is not comparing the labs’ best against each other. Match the tier to the job before trusting any ranking.
Which AI should you actually pick?
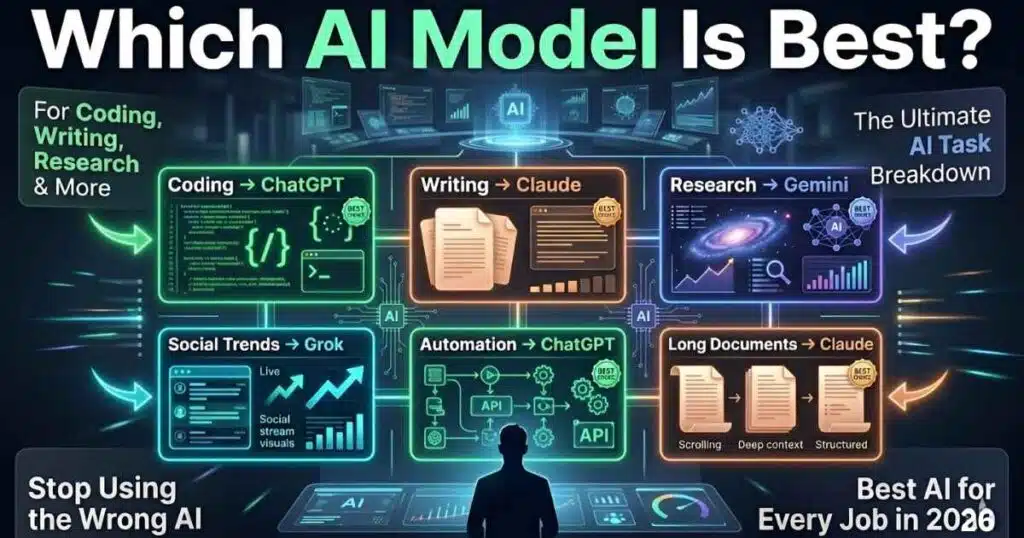
Forget “best” and match the model to the task:
- Hard coding and deep debugging: Claude Opus 5.5 — index leader, pairing with Claude Code for terminal-based agent work. Grok 4.7 is a credible second; Codex with GPT-6.1 Sol fits stacks already on OpenAI.
- Long documents, research, careful writing: Claude again — the 1M-token context across the 5.5 family swallows a codebase or contract stack, and Sonnet 5.5 gives near-flagship quality at half the price.
- Breaking news, live markets, social sentiment: Grok 4.7 — native X and web search are its reason to exist.
- Cheapest API bill at scale: GPT-6.1 Sol ($2 / $10, measured $0.72 per task); for high-volume simple work, GPT-6 Luna or Claude Haiku 5.5 at $0.10 / $0.50 per million.
- Desktop automation and integrations: ChatGPT — native computer use and 500+ integrations are unmatched.
- Finished deliverables: Grok’s native PDF, PPTX, and XLSX output skips the copy-paste step.
- Tightest budget: ChatGPT Go and Grok Plus both cost $8 a month; Claude’s free tier runs Sonnet and Haiku, but Opus needs Pro at $20.
The verdict: Claude vs ChatGPT vs Grok in 2026
Claude Opus 5.5 is the strongest model by independent measurement — the pick when a wrong answer is expensive. ChatGPT is the best all-around product: the largest ecosystem, native computer use, and the GPT-6 generation’s best cost per task. Grok 4.7 is the pick when information is fresh or output is heavy. Ignore any comparison still quoting GPT-5.5, Claude Opus 4.x, or Grok 4.3 as current — those are legacy models.
Frequently asked questions
Which is best for coding, Claude vs ChatGPT vs Grok?
Claude Opus 5.5 leads the independent Artificial Analysis Intelligence Index at 57.6 and pairs with Claude Code for terminal-based agent work — the strongest coding pick overall. Grok 4.7 is close behind at 38.0% on Terminal-Bench 4.0; teams on OpenAI’s stack should pick Codex with GPT-6.1 Sol.
Which AI chatbot is cheapest for API use in 2026?
GPT-6.1 Sol is the cheapest per completed task at a measured $0.72, on a $2 input / $10 output rate card. The cheapest per-token options are GPT-6 Luna and Claude Haiku 5.5 at $0.10 / $0.50 per million tokens, for high-volume simple work. Grok 4.7’s $2 / $6 card looks cheap, but its verbosity raises real bills.
Is ChatGPT still the best all-around AI chatbot in 2026?
For most people, yes: 900M+ weekly users, 500+ integrations, native computer use, and image generation — capabilities the others only partly match. Since October 7, paid Chat subscribers get GPT-6 Sol and Free/Go users get GPT-6 Luna, with GPT-6.1 Sol in Work, Codex, and the API.
Claude vs ChatGPT vs Grok: which is best for real-time news and current events?
Grok 4.7, clearly. Its native X and web search pulls live information straight into answers — the feature xAI built it around. ChatGPT’s browsing is manual rather than native, and while Claude can search the web, neither matches Grok’s speed on breaking topics.
Are the older models — GPT-5.5, Claude Opus 4.7, Grok 4.3 — still usable?
Mostly as legacy options — do not build anything new on them. OpenAI retired GPT-5.5 from Chat, Work, and Codex on October 14, 2026 (API only). Anthropic lists the entire Opus 4.x line, including Opus 4.7, as legacy. Grok 4.3 has been superseded by Grok 4.6 and 4.7.
Abdul Manan is a professional SEO content creator and AI-SEO strategist at seofyai.com. He specializes in helping businesses rank higher on Google through AI-powered, data-driven content optimization. Connect on LinkedIn or visit seofyai.com for expert SEO tips.